
Goldman Sachs Data Engineer Jobs in Bengaluru 2026: Lakehouse & AI Data Platform Engineer (Analyst)
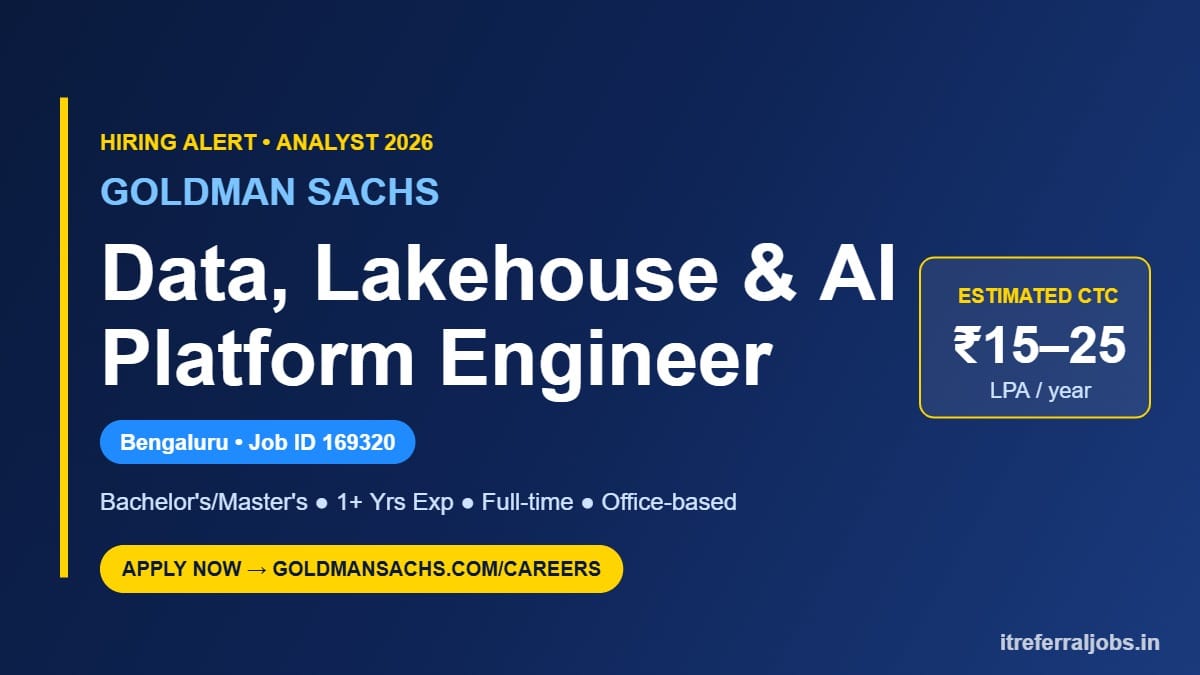
Goldman Sachs has opened applications for one of the most sought-after Goldman Sachs data engineer jobs of the season — the Software Engineering – Data, Lakehouse & AI Data Platform Engineer (Analyst) role at its Bengaluru, Karnataka office. Posted on 14 May 2026 under Job ID 169320 on the firm’s official lateral hiring portal, this opening targets engineers with 1+ years of experience who want to build production-grade data pipelines that power decision-making at one of the world’s leading investment banks. In this guide you will find the verified job overview, eligibility criteria, an industry salary estimate, interview preparation pointers, and the official application link.
Job Overview
| Company | Goldman Sachs |
| Job Role | Data, Lakehouse & AI Data Platform Engineer (Software Engineering – Analyst) |
| Job ID | 169320 |
| Job Category | Analyst – Data Engineering |
| Qualification | Bachelor’s or Master’s degree in a relevant discipline (or equivalent practical experience) |
| Experience | 1+ years |
| Job Location | Bengaluru, Karnataka, India |
| Work Mode | Office-based (Bengaluru) |
| Job Schedule | Full-time |
| Salary | ₹15 – ₹25 LPA (industry estimate, AmbitionBox/Glassdoor 2026 benchmarks) |
| Posting Date | 14 May 2026 |
| Hire Eligibility | Engineers with hands-on Python/Java + SQL experience; 2024/2025 graduates with 1+ years of work experience may apply |
| Last Date | Not declared — apply early (role can close once filled) |
About Goldman Sachs
Founded in 1869 and headquartered at 200 West Street, New York, Goldman Sachs is one of the world’s premier investment banking, securities, and asset management firms. The firm serves corporations, governments, financial institutions, and individuals across every major market, and is consistently ranked among the most prestigious employers in global finance.
The Bengaluru office is one of Goldman Sachs’ largest engineering hubs outside the United States. Thousands of engineers in India build and operate the firm’s trading, risk, and data platforms, which makes the location a genuine product-engineering centre rather than a back-office outpost. For data engineers, this means direct exposure to petabyte-scale financial datasets, modern lakehouse tooling, and global engineering standards.
Job Description
As a Data Engineer in the Lakehouse and AI Data Platform team, you will design, build, test, and support data pipelines and curated datasets on the firm’s modern data platform. The work spans the full lifecycle — ingestion, transformation, modelling, optimisation, and data quality — with the goal of shipping data products that analytics, reporting, and AI teams can rely on. Where the platform has gaps, you may also build shared tooling or framework components that improve how the platform is used and operated. The official posting notes that stronger candidates can additionally contribute to technical design, platform standards, and delivery approaches across wider use cases.
Key Responsibilities
- Build, enhance, and support batch and streaming data pipelines on the Lakehouse and AI data platform.
- Refactor and modernise existing data flows to improve reliability, performance, and maintainability.
- Develop raw, refined, and curated datasets that serve analytics, reporting, and AI use cases.
- Apply sound data modelling principles — temporal data, schema evolution, partitioning, and clustering — to represent business entities accurately.
- Implement data quality controls validating completeness, accuracy, and consistency across pipelines.
- Run reconciliation checks on production outputs and investigate breaks through root-cause analysis.
- Ensure pipelines are production-ready, well tested, and operationally supportable under CI/CD discipline.
- Collaborate with data consumers to shape well-documented data products aligned to business needs.
Eligibility Criteria
You Must Have
- Bachelor’s or Master’s degree in a relevant discipline, or equivalent practical experience with strong quantitative skills.
- 1+ years of experience with strong hands-on programming in Python or Java.
- Good working knowledge of SQL, including troubleshooting, optimisation, and data analysis.
- Familiarity with software engineering fundamentals — version control, testing, release discipline, and CI/CD practices.
- Ability to learn new tools, internal platforms, and delivery workflows quickly.
Preferred
- Experience with distributed processing frameworks such as Apache Spark, and streaming with Kafka.
- Working knowledge of data formats like JSON, Avro, and Parquet.
- Exposure to Snowflake, Apache Iceberg, Databricks, or Hadoop ecosystem technologies.
- Understanding of temporal data modelling, schema evolution, and performance techniques like partitioning and clustering.
- Experience guiding code quality or leading delivery for a workstream.
Goldman Sachs Data Engineer Salary in India 2026
Goldman Sachs does not publish compensation in the job posting, so treat the following as an industry estimate based on AmbitionBox and Glassdoor 2026 benchmarks. Analyst-level data engineers in Bengaluru with 1–3 years of experience typically earn in the range of ₹15 – ₹25 LPA including base pay and performance bonus. Engineers with niche lakehouse or AI-platform skills tend to land at the upper end of that band. Actual offers vary with interview performance, skill depth, and internal banding, so use this range only for planning your expectations.
Interview Preparation Tips
- DSA & coding: practise medium-level problems in Python or Java — arrays, hash maps, strings, and time-complexity trade-offs come up frequently.
- SQL depth: be ready to write window functions, optimise slow queries, and reason about indexes and partitioning.
- Data engineering design: revise batch vs streaming trade-offs, Spark internals, schema evolution, and lakehouse table formats like Iceberg.
- OOPs & testing: explain clean-code principles, unit testing strategy, and how you ship via CI/CD.
- Projects: prepare one pipeline project end-to-end — ingestion, modelling, data quality checks, and the business outcome it served.
- Behavioural: Goldman Sachs values ownership and structured problem solving — use the STAR format with measurable results.
How to Apply for Goldman Sachs Data Engineer Jobs (Job ID 169320)
- Open the official Goldman Sachs lateral hiring portal using the apply link below.
- Review the complete job description for Job ID 169320 and click Apply Now.
- Sign in or create your candidate profile on the portal.
- Upload an updated, ATS-friendly resume highlighting Python/Java, SQL, and pipeline projects.
- Fill in your education, experience, and skill details accurately — they are matched against the JD.
- Review everything once and submit your application, then track status from your profile dashboard.
Apply Now — Goldman Sachs Careers Portal (Job ID 169320)
Disclaimer: Apply only on the official Goldman Sachs careers portal linked above. Goldman Sachs never charges any fee at any stage of recruitment. Beware of fake recruiters, paid “referral guarantees”, or unofficial portals asking for money or OTPs. Salary figures above are estimates, not confirmed offers.
You may also explore similar live openings on IT Referral Jobs, such as the HCLTech Off Campus Drive 2026 for AI Engineers and the TransUnion Associate Engineer Jobs in Chennai & Pune.
Career Toolkit
Boost your application with these free tools:
- Resume Builder: https://careertoolkit.in/resume-builder/
- ATS Score Checker: https://careertoolkit.in/ats-score-checker/
- Cover Letter Generator: https://careertoolkit.in/cover-letter-generator/
- Salary Estimator: https://careertoolkit.in/salary-estimator/
- Certification Suggestion: https://careertoolkit.in/certification-suggestion/
- Interview Preparation: https://careertoolkit.in/interview-preparation/
FAQs
1. Who can apply for this Goldman Sachs Bengaluru data engineer role?
Candidates with a Bachelor’s or Master’s degree (or equivalent practical experience), at least 1 year of experience, and strong Python or Java plus SQL skills can apply.
2. Can 2025 or 2026 freshers apply?
The posting asks for 1+ years of experience, so absolute freshers are not the target. Recent graduates with one year of internship-plus-work experience in data engineering can still try.
3. Is this a remote or hybrid job?
The role is based at the Goldman Sachs Bengaluru office. The posting does not advertise a remote option; expect office-based work as per team policy.
4. What is the expected salary?
Goldman Sachs has not disclosed pay. Based on AmbitionBox and Glassdoor 2026 benchmarks, comparable Analyst-level data engineers in Bengaluru earn roughly ₹15 – ₹25 LPA.
5. What is the selection process?
Typically an online coding assessment followed by 2–3 technical rounds (DSA, SQL, data engineering design) and a behavioural/HR discussion. The exact process can vary by team.
6. Is there any application fee?
No. Goldman Sachs never charges candidates at any stage. Treat anyone asking for money as a scam.
7. Which skills give the strongest edge?
Spark, Kafka, Snowflake/Iceberg/Databricks exposure, solid SQL optimisation, and a production pipeline project you can explain end-to-end.
8. How long will the role stay open?
No last date is declared. Lateral roles close once a hire is made, so applying early improves your odds.
Conclusion
This Analyst opening is a strong match for early-career engineers who want world-class data platform exposure inside global finance. If you meet the eligibility above, polish your resume with the toolkit links, apply on the official portal today, and keep following IT Referral Jobs for more verified Goldman Sachs data engineer jobs and other high-quality openings across India.
Curated and verified by the IT Referral Jobs editorial team.

1 thought on “Goldman Sachs Data Engineer Jobs Bengaluru 2026 | Apply Now”